

Anthropic launched Claude Sonnet 5.5 on September 28, 2026, six days after Opus 5.5. Pricing does not move from Sonnet 5, $2 per million input tokens and $10 per million output tokens, but the model generates output more than 30% faster and uses fewer tokens per task. On Terminal-Bench 4.0, it jumps from 10.3% to 70.6% and even moves ahead of Opus 5.5. The official charts show it costs less than Opus 5.5 at low and medium effort, then loses that advantage beyond.
What Claude Sonnet 5.5 changes compared with Sonnet 5
Sonnet 5.5 is the second model in the Claude 5.5 family, ahead of Haiku 5.5, announced for the coming weeks. It keeps a 1 million token context window, 128,000 output tokens and reliable knowledge up to June 2026. Its ID is claude-sonnet-5-5 on the Claude API, Google Cloud and Microsoft Foundry, and anthropic.claude-sonnet-5-5 on Amazon Bedrock.
Introducing Claude Sonnet 5.5, the second model in the Claude 5.5 family. It’s a clear upgrade over Sonnet 5, runs more than 30% faster, and costs up to 30% less for most work.
— Claude (@claudeai) September 28, 2026
Unchanged pricing, fewer tokens per task
Anthropic does not cut the price per token, it cuts the number of tokens needed. According to the company, a typical task costs up to 30% less than with Sonnet 5. Here is the published price list, set against the Opus 5.5 one:
| Item, per million tokens | Sonnet 5.5 (Opus 5.5) |
|---|---|
| Input | $2 ($4) |
| Output | $10 ($20) |
| Cache reads | $0.20 ($0.20) |
| 5-minute cache writes | $2.50 ($5) |
| 1-hour cache writes | $4 ($8) |
| Batch processing | $1 input, $5 output |
One detail stands out: cache reads cost exactly the same on both models, because Opus 5.5 gets a reduced rate of 0.05 times input. In an agentic session dominated by cache reads, the price gap between Sonnet and Opus therefore narrows sharply. The full Claude pricing guide also covers the subscriptions.
Faster, and designed as a complement to Opus 5.5
Sonnet 5.5 is the fastest Sonnet to date, generating output more than 30% faster than Sonnet 5. Anthropic positions it on well-scoped everyday tasks: fixing bugs and producing polished documents, slides and spreadsheets. Opus 5.5 remains the recommendation for complex work that needs sustained judgment.
The default effort setting depends on where you use it. It is medium in the Claude apps and in Claude Code, and high on the API.
The official benchmarks against Sonnet 5 and Opus 5.5
The values below come from Anthropic’s official announcement of September 28, 2026. They compare Sonnet 5.5 with Sonnet 5, Opus 5.5 and whichever OpenAI model was available on each test.
Coding: a leap from Sonnet 5
Coding is where the gap with the previous generation is most striking:
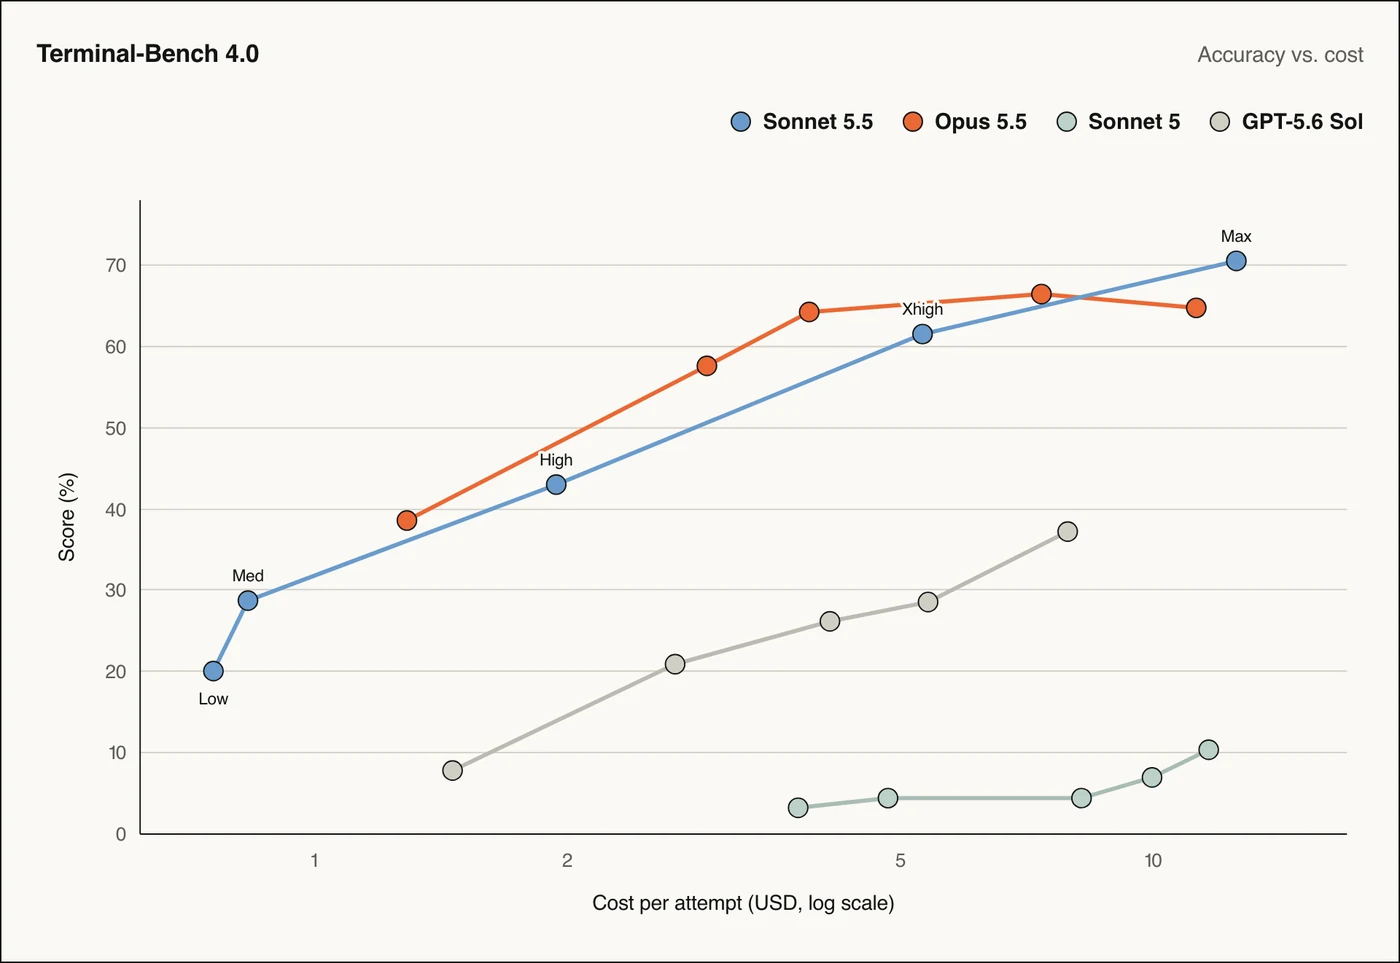
- Terminal-Bench 4.0: 70.6% at max effort, versus 10.3% for Sonnet 5 and 66.4% for Opus 5.5 at its best setting;
- CursorBench 4.0: 55.5%, versus 34.1% for Sonnet 5 and 57.8% for Opus 5.5;
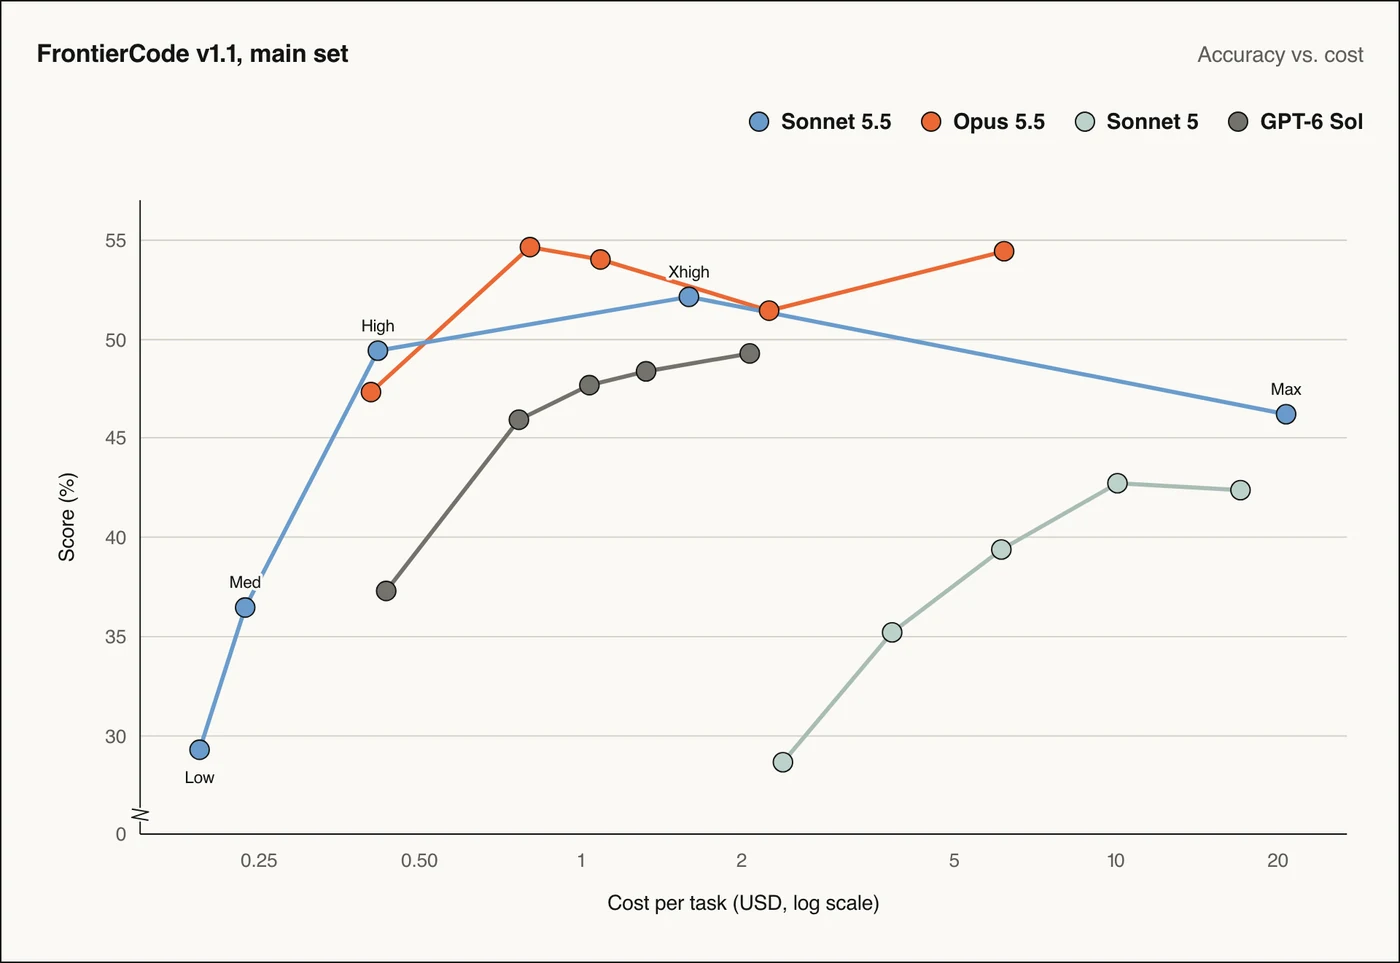
- FrontierCode v1.1: 52.1% at xhigh effort and 46.2% at max, versus 42.4% for Sonnet 5, 49.3% for GPT-6 Sol and 54.4% for Opus 5.5.
Look at what that Terminal-Bench score costs, though. The 70.6% comes at $12.54 per attempt, while Opus 5.5 reaches 66.4% for $7.35 and 64.2% for $3.88. At medium effort, Sonnet 5.5 does not go above 28.8%.
Office work, vision and computer use
Outside coding, Sonnet 5.5 stays very close to Opus 5.5 on most rows:
- GDPval-AA v2.1: 1844 Elo, versus 1846 for Opus 5.5 and 1449 for Sonnet 5;
- AA-Briefcase v1.1, a new test of long-horizon office work: 1811, versus 1822 for Opus 5.5 and 1359 for Sonnet 5;
- OSWorld 2.1, operating a computer: 80.1%, versus 81.8% for Opus 5.5 and 57.0% for Sonnet 5;
- Chartography, reading charts without tools: 61.6%, versus 64.4% for Opus 5.5 and 15.6% for Sonnet 5;
- Humanity’s Last Exam with tools: 64.5%, versus 67.7% for Opus 5.5.
Anthropic adds that Sonnet 5.5 is the first Sonnet to beat Pokémon Red working only from screenshots. Do not rely on scores alone, though: in its own testing, the company finds Opus 5.5 clearly stronger on open-ended work that needs sustained judgment.
Sonnet 5.5 or Opus 5.5: it all depends on the effort level
The announcement’s charts plot each model at its five effort levels, with the score reached and the cost per task. Crossing them gives a clear rule for choosing between the two models.
At low effort, Sonnet 5.5 costs less
On FrontierCode, Sonnet 5.5 at high effort scores 49.4% for $0.42, slightly more than Opus 5.5 at low effort, 47.3% for $0.40. On AA-Briefcase, Sonnet 5.5 at high reaches 1634 for $3.95, while Opus 5.5 at medium gets 1642 for $4.40. If your tasks are simple and repetitive, keep Sonnet 5.5 at a moderate setting: that is where it saves you money.
The comparison with Sonnet 5 is even clearer. Anthropic says that at low or medium effort, Sonnet 5.5 beats Sonnet 5’s best score for about a tenth of the cost per task, on several tests.
Beyond high, Opus 5.5 is cheaper
As soon as you raise the effort, the trend reverses. At a comparable score, Opus 5.5 at a lower setting costs less than Sonnet 5.5 at a higher one:
| Test and settings | Sonnet 5.5 versus Opus 5.5 |
|---|---|
| Terminal-Bench, xhigh versus high | 61.5% for $5.30, versus 64.2% for $3.88 |
| FrontierCode, xhigh versus medium | 52.1% for $1.59, versus 54.6% for $0.80 |
| CursorBench, max versus high | 55.5% for $9.67, versus 56.0% for $3.97 |
| AA-Briefcase, max versus max | 1811 for $29.19, versus 1822 for $21.05 |
Anthropic half admits it: Sonnet 5.5 complements Opus 5.5 best at lower settings, and at higher settings it performs comparably at a similar cost. The numbers show the cost is often higher.
On CursorBench, Sonnet 5.5 at max effort scores 55.5% for $9.67 per task, while Opus 5.5 at high effort scores 56.0% for $3.97. Beyond high, switch to Opus 5.5.
Max effort sets Sonnet 5.5 back on FrontierCode
On FrontierCode, Sonnet 5.5 scores 52.1% at xhigh for $1.59, then drops to 46.2% at max for $20.78. Anthropic explains it in a footnote: at max, the model more often runs Claude Code’s code-review skill, split across many subagents, which led to timeouts or to edits beyond the task’s scope.
Artificial Analysis notes that Sonnet 5.5 shows, on its index, the highest number of output tokens per task it has ever measured. Keep that setting for cases where your own evaluations show a real gain.
Anthropic has launched Claude Sonnet 5.5: it scores 56 on the Artificial Analysis Intelligence Index, just 2 points behind Opus 5.5 (max), but at the highest Output Tokens per Task we’ve seen
— Artificial Analysis (@ArtificialAnlys) September 28, 2026
API breaking changes before migrating from Sonnet 5
The Sonnet 5.5 migration documentation lists five changes that return an error on code that worked with Sonnet 5:
- Thinking can no longer be turned off with disabled. Send
thinking: {"type": "between_tools"}, accepted at low, medium and high effort only; at xhigh and max effort, it returns a 400 error. - Forced tool use is rejected. A
tool_choiceof typeanyortoolreturns a 400 error; keepautowith strict mode. - Thinking blocks are tied to the model, the conversation and the account. Sonnet 5.5 reads those from Sonnet 5 and older models, but no other model reads its blocks, and they only work in the account that produced them.
- The older computer_20251124 tool is rejected on the Claude API and Google Cloud, in favor of the
computer_toolset_20260801toolset. - The advisor tool rejects some advisors. Opus 4.8, Opus 4.7 and Sonnet 5 are no longer accepted as advisors for a Sonnet 5.5 executor.
What Sonnet 5.5 adds over Sonnet 5
Sonnet 5.5 gains features Sonnet 5 lacked: per-message effort, mid-conversation system messages and mid-conversation tool changes. The minimum cacheable prompt also drops from 1,024 to 512 tokens.
Finally, the short notes written between tool calls arrive in thinking blocks that are empty by default. If your interface shows those progress messages, set thinking.display or switch to between_tools mode.
Safeguards and availability
The first Sonnet with cybersecurity safeguards
Sonnet 5.5’s cybersecurity capabilities match those of Opus 5, which makes it the first Sonnet to launch with cyber safeguards and an automatic fallback. Higher-risk requests visibly fall back to Sonnet 5, but finding and fixing bugs in your own code remains possible. Biology safeguards stay the same as Sonnet 5’s.
The model remains available with zero data retention, like Opus 5.5 and Sonnet 5. The Sonnet 5.5 system card details the alignment and safety evaluations.
Where can you use Sonnet 5.5 today?
The model is open to everyone on Claude.ai, on the web, iOS and Android, as well as on the Claude API and the three major clouds. Cursor added it on release day.
Sonnet 5.5 is now available in Cursor! It’s a strong model, performing on par with Opus in many tasks.
— Cursor (@cursor_ai) September 28, 2026
To understand the tier above, the Claude Opus 5.5 analysis details its cost per task at each effort level. To see how the agent that runs these models in your terminal works, read the Claude Code guide.

